Last updated: 2026-10-30

OpenClaw & Claude Code News & Video Summaries

Every OpenClaw story we've covered — releases, tutorials, and analysis, summarised from the community and the official changelog. 275 and counting. New summaries are published as videos drop.

Looking for guides instead? See the OpenClaw hub.

Ten GitHub repos for Claude Code worth installing, the tips for each, and the token-saving tools he says to skip

Nate Herk's shortlist of ten repos for Claude Code after testing over a hundred: Hyperframes, the Google Workspace CLI, the Apify MCP server, Scrollcraft, Humanizer, Addy Osmani's agent skills, Expo, Supabase and Stripe skills, Playwright CLI, Claude Security and Open SEO, plus which token-saving repos he says to skip. Two install paths checked against GitHub.

Pi Durable: coding agents that survive failures, share state, run resumable tasks and attach from any client

A walkthrough of Pi Durable, the experimental release for the Pi coding agent: detached agents you reconnect to from a terminal or browser, shared application state, resumable tasks with approval steps, background compaction, tool sets you can change mid-session, extensions, forking, and a proactive incident-response demo. Official documentation was not found, so details are the presenter's.

Agent Native: an open-source framework where you and the agent edit the same app, with shared actions, context and a slides template

A hands-on look at Agent Native, an open-source TypeScript framework from Builder: build a deck with the Slides app, edit it by hand, ask the agent to continue from your changes, then scaffold your own copy, read the defineAction and context code, and extend it with a coding agent. Create command, license and actions API checked against the repository.

Why Reducto deleted its one-tool-per-endpoint MCP server and rebuilt it with fewer, workflow-shaped tools

Reducto's Abhi Arya describes an MCP server that worked in a demo and broke the moment the whole team used it: the agent built whole pipelines confidently and nobody could explain them. The fix was architecture, not prompting: fewer tools that carry the structure of real work, a snapshot tool for stateless agents, confidence data surfaced to the model, and ask-instead-of-guess.

Haiku 5.5 vs Sonnet 5.5 and Opus 5.5 on a dozen builds: what each cost, and where the gap was small

Nick Saraev spent over $700 giving Claude Haiku 5.5, Sonnet 5.5 and Opus 5.5 the same prompts: games, sites, an accounting-fraud audit and a finance app. Haiku cost a fraction (fifths to hundredths) and often looked close; Opus won the games. His routing advice: let a frontier model plan and use Haiku as the hands for summaries, classification and database queries.

Brains vs hands: let the agent plan and a deterministic harness execute

Orkes' Viren Baraiya argues that in production the LLM should only propose the next steps while a deterministic, durable harness does the executing, so every cluster restart, payment or approval runs the same way each time. He demos an SRE remediation loop that compiles an agent's plan into a Conductor workflow. A vendor talk, with no code shown.

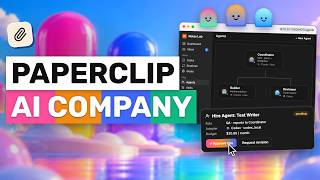
Paperclip, step by step: a small agent team with review gates, budgets and heartbeats

AICodeKing walks through Paperclip, an open-source app that sits above Claude Code, Codex and other agents to assign tasks, pass work between them, enforce a review stage and cap spending. He sets up a small notes-app team and is candid about the limits: budgets are not a guarantee, tool permissions don't cover every shell command, and a CEO agent doesn't make good decisions.

CodeAF tested with local Ollama: parallel tasks, three-model crews, spend tracking and the rough edges

Fahd Mirza installs CodeAF, a single-binary Go coding harness that splits work into tasks, checks them and merges what passes, and tests it against a local Ollama model and an OpenRouter model. Parallel tasks and three-role crews (planner, worker, checker) worked; first-run defaults and model selection were clunky. His verdict: promising but too young to be a daily driver.

Separate a video subject from its background with a Claude Code skill, then edit scene by scene in an HTML review panel

Bart Slodyczka runs a free skill that has Claude Code download Meta's Segment Anything model, track a subject through every frame of a clip, and split it from the background so you can put text behind it, dim the background or pin a label to a moving object. He also shows an HTML page that lists each scene with a comment box for batch edits. It must run in Claude Code, not Cowork.

Vercel's fx: a 6 MB Unix-style coding agent, and how its author uses it

In an interview, Vercel's CEO shows how he works with fx, Vercel Labs' tiny native coding CLI: a one-letter alias that opens a research folder with an AGENTS.md convention, a project-scaffolding alias, agent 'inquiries' that try to break new infrastructure, and an embeddable harness with the model as brain and a sandbox as hands. This summary covers the first 40 minutes of a longer interview.

Jev tested: 98% to 3% on negation, a forced wrong answer at 0.31, and a 7-second browser run

Eight hands-on Jev tests: support routing with four questions at once, negation handling that drops a refund probability from 98% to 3%, a forced-choice failure that returns the wrong department at 0.31 confidence, a prompt-injection attempt that fails to flip the classification, value extraction from candidates, and an agent-trace audit. Plus Jev Ultrafast, which drove a Google Flights search in about seven seconds for $0.0039.

DeepSeek V4.1 Flash vs GPT-6 Astra on real builds: 4–6× cheaper, 3–5× slower

Same prompts, paid OpenRouter API, measured cost and wall-clock time across a game, an animated website and a booking app. Astra: $12.25/47 min, $48.63/2h10m, $17.88/41 min. DeepSeek V4.1 Flash: $3.30/4h14m and $7.74/about 7.5h on the first two. Astra's first drafts needed fewer fixes; DeepSeek got there with more iterations.

Pick models with five benchmarks, not one index: Terminal Bench, Apex Agents, Automation Bench, Omniscience, Deep SWE

Instead of the blended Artificial Analysis index, choose models from five benchmarks matched to your work, weighing performance, cost and speed together. Astra leads Terminal Bench at about 4× lower cost than Fable 5.1. Automation Bench penalises guardrail violations, where Fable and Opus drop. Gemini 3.8 Flash and GLM 5.3 Flash stand out as low-cost workhorses.

The instruction ceiling moved 10x in a year: 200 rules became 2,000

A re-run of the IFScale benchmark against current frontier models. A year ago models started dropping instructions at 200-300; today the boundary is closer to 2,000 and the best reach 5,000. The failure modes also changed, and one of them is a refusal rather than a forgetting.

ACP is MCP's missing half: a standard for telling a harness what to do

An MCP maintainer argues that agents have a standard for reaching out to tools but none for client software to control the harness itself, and presents the Agent Client Protocol — its design, its new remote transport, and what becomes possible once every piece of the stack can be moved.
A browser agent with two kinds of skill file — yours, and everyone's

A walkthrough of Retriever, a browser-based task agent, focusing on the part worth knowing about regardless of the tool: it keeps personal skills as editable markdown describing how you want to work, and a separate set of shared website skills capturing how to navigate a given site.

Running agent swarms with hard spend caps, and why the answer is a sandbox

A working demonstration of self-hosted agent swarms, from a one-agent hello world to 30-agent runs, each pinned to a specific model with an explicit dollar ceiling. The framing is deliberately unglamorous: swarms are viable, expensive and dangerous, and the controls matter more than the capability.

OmegaClaw tested: a symbolic-logic agent installed with one Docker command

A hands-on install and test of OmegaClaw, an open-source agent framework from SingularityNET whose core runs on a formal symbolic layer rather than wrapping a model in Python. The run verifies the two claims that matter: memory that survives a container restart, and a symbolic reasoning layer that computes a confidence value rather than asserting one.

GPT-6 Astra vs Fable 5.1 across 15 use cases, with cost and time for each

A head-to-head of GPT-6 Astra and Claude Fable 5.1 across fifteen everyday tasks, recording which model produced the better output plus the wall-clock time and dollar cost of each run. The consistent structural finding is that Astra asks clarifying questions before starting where Fable takes the prompt and runs.

GPT-6 Astra vs Fable 5.1: five identical builds, and a looks-versus-works split

The same five prompts given to GPT-6 Astra and Claude Fable 5.1 in parallel — a full-stack CRM as a native Mac app, a Notion clone, a clothing brand storefront, a 3D city model, and an Age of Empires II replica. Every session produced a working app with no steering, and the differences fall into a consistent pattern.

The five pieces of a real agent: harness, MCP, skills, sandbox, production layer

A plain-English breakdown of what an agent is made of beyond the model — the harness that runs the loop, MCP as the tool protocol, skills as loaded-on-demand instructions, the sandbox for code execution, and the production layer of subagents, approvals and observability — followed by a live build using an open-source harness.

Four documented ways to prompt Fable 5.1 that cut how fast you burn your limits

Four prompting techniques pulled from Anthropic's own Fable 5.1 documentation, with the supporting quotes: describe the finished state rather than the task list, match effort level to the work instead of leaving it on high, make the model verify its own output before handing it to you, and delegate to parallel subagents so the flagship drives strategy rather than doing the work.

Inside an agentic engineering setup after 6,775 sessions

A full walkthrough of one practitioner's agentic engineering stack: the interfaces used to run many agents at once, how to combine subscriptions instead of paying API rates, and a step-by-step build of self-hosted cloud agents on a VPS driven entirely by an agent in plain English.

Fable 5.1's published benchmarks: AutomationBench nearly doubles

A same-day read of Anthropic's published benchmark numbers for Fable 5.1 against Fable 5, Opus 5 and GPT-5.6 Sol, with the business-workflow score standing out — AutomationBench moves from 17.1% to 31.4%, roughly doubling — plus the shift toward measuring cost per task rather than cost per token.

Give any coding agent a spoken reply using a CLI and a Stop hook

A small, portable trick: install a text-to-speech CLI, then instruct your coding agent to invoke it when a task finishes so it speaks a one-or-two sentence summary and a next-step question instead of adding to a wall of text. Works across harnesses because the agent is just running a command.

OpenClaw 2.0 review: the upgrade broke, and the new features are web-app only

A critical review of OpenClaw 2.0 from someone who left the project four months ago over update reliability. Covers the eight headline features, the in-place upgrade failing again and forcing a clean install, and the significant limitation that most of the new functionality exists only in the web app.
Context as Code: Inside a Markdown-First Agent Content Machine

Alex Lieberman and Dan of 10X break down a content pipeline built entirely from skills and markdown — a process layer in git, a personal voice layer on disk, six interviewer personas as six skills, an editor council with a 9-out-of-10 gate, and a lessons file the agent re-reads before every write.

Who Owns Your AI Agent? The Maintenance Skill Teams Skip in 2026

Nate B Jones argues the critical 2026 agent skill isn't building — it's ownership and 'care and feeding.' Any system that reads real context, produces work you act on, or touches a shared workflow needs a named owner. He gives a simple operating model: give each agent a job, a diet, boundaries, and a review loop, plus an 'owner card' / agent registry for teams.

Open Skills: Portable, Composable Agent Procedures Across Every Tool

Nate B Jones launches Open Skills — a public library of 31 reusable agent procedures (plus 7 runbooks) packaged as skill.md files that travel across Claude Code, Codex, Cursor, and any harness. The pitch: stop re-explaining how you work to every new agent — encode procedures once, scope them, compose them into runbooks, and bake verification into the contract.

How to Set Up GLM 5.2 in Claude Code (~5x Cheaper Than Opus)

Nate Herk swaps Claude Code's model engine for Z.AI's open-source GLM 5.2 by editing one settings.local.json file — routing ANTHROPIC_BASE_URL to Z's API. He covers pricing (~5x cheaper than Opus 4.8), where GLM wins and loses against Opus, and a per-directory trick to keep GLM and Opus projects side by side.

The 5 Levels of a Claude Code Second Brain (Memory & Context Engineering)

Nate Herk breaks the AI 'second brain' into five levels — from a simple CLAUDE.md router and markdown folders, up through LLM wikis, semantic/vector search, knowledge graphs, and full autonomy. The key lesson: pick the lowest level that solves your actual pain, and design your folders around how you'll retrieve the data later.

Idea to Deployed AI App with Claude Code, the Vercel AI SDK, and design.md

Developers Digest walks through his go-to stack for shipping an AI app fast: Claude Code scaffolds a Next.js + Vercel AI SDK ChatGPT-style clone, routes models through the Vercel AI gateway, and then deploys it end-to-end — creating a private GitHub repo and wiring up auto-deploy on every push — all driven by natural language with almost no hand-written code.

GLM-5.2 vs Opus 4.8 in Claude Code: Near-Parity Output at a Fraction of the Cost

Nick Saraev pits the open-weight GLM-5.2 against Opus 4.8 across roughly 40 creative coding scenes — 3D/WebGL, interactive explainers, dashboards, landing pages and mini-games — and finds GLM frequently matches or beats Opus on visual "taste." He then walks through the simplest way to run GLM-5.2 inside the Claude Code harness (plus Open Code and Crush) via OpenRouter, and ranks the most cost-effective providers.

Build 3 Production AI Agents in Python with AgentSpan: Memory, RAG, and Orchestration

Tech With Tim builds three Python agents on the open-source AgentSpan framework — a conversational agent with memory, a RAG agent over a company database, and a multi-agent orchestrator — each written line by line. The focus is what makes an agent production-ready: durability across crashes, retries, human-in-the-loop, observability, long-running tasks and scale, all handled by a local AgentSpan server.

Agent Loops Explained: Reason–Act–Observe Cycles Instead of One-Shot Prompting

Nate Herk demystifies "loop engineering" — the idea that instead of prompting a coding agent yourself, you design a loop that prompts the agent. A loop is a trigger, an action, and a stop condition, built on two pillars: an objective goal and a verification method. He argues most tasks don’t need elaborate agent swarms — a single reason–act–observe loop with a good "definition of done" does most of the work.

Why Better Models Can Break Your Agents: The Case for Harness Maintenance

Nate B Jones uses Vercel’s sales agent — which got better after the team deleted 80% of its tools — to argue the real 2026 agent story is maintenance, not building. The "harness" (the workbench around the model: sources, memory, tools, permissions, proof, stop conditions) must be continuously pruned and rebuilt, because agents break in two directions: the world around them drifts, and the model inside them improves.

Rank #1 with OpenClaw + Hermes AI SEO Agent Swarm

A multi-agent SEO system using OpenClaw and Hermes automates keyword research, content writing, and WordPress publishing on a schedule. A 12-agent swarm handles competitor analysis, technical SEO, and backlink planning simultaneously.

Run Claude Code Free with OpenRouter in 5 Minutes

A free middleware project bridges Claude Code to any model on OpenRouter, including free-tier options, in about five minutes. Install a helper, add an OpenRouter key, and run Claude Code normally — no paid subscription required.

How to Build a Claude Opus 4.8 AI Operating System

Nate Herk shares his four C's framework for building a personal AI operating system on Claude Code with Opus 4.8: context, connections, capabilities, and cadence — and why context beats model choice every time.
← Back to the full news digest · Browse the OpenClaw guides